Summary Quick-View
The loquacious era of artificial intelligence—where every computational problem was met with a paragraph of polite, hallucination-prone prose—is facing a silent revolution. For years, we have been captivated by Large Language Models (LLMs) that are, in the words of TypeSafe AI co-founder and OpenAI veteran Diogo Almeida, “superhuman at pleasing humans.” But as any enterprise architect will tell you, a model that is great at chatting is often a disaster at acting.

The bottleneck isn’t intelligence; it’s the “computational tax” of conversation. Current frontier models are slow, expensive, and optimized for human preference via RLHF (Reinforcement Learning from Human Feedback). For real-world software automation, we don’t need a bot that wants to be our friend; we need a “probabilistic engine” that can make a decision in the blink of an eye.
Enter Jev, a new model from San Francisco-based TypeSafe AI. Jev doesn’t write poetry, it doesn’t debug your code with a friendly “Sure, I can help with that!”, and it refuses to speak a single word. Instead, it classifies and decides. By abandoning the gift of gab, Jev has unlocked a level of speed and efficiency that suggests the most important part of the AI revolution might actually be silent.
1. The Rise of “System One” AI
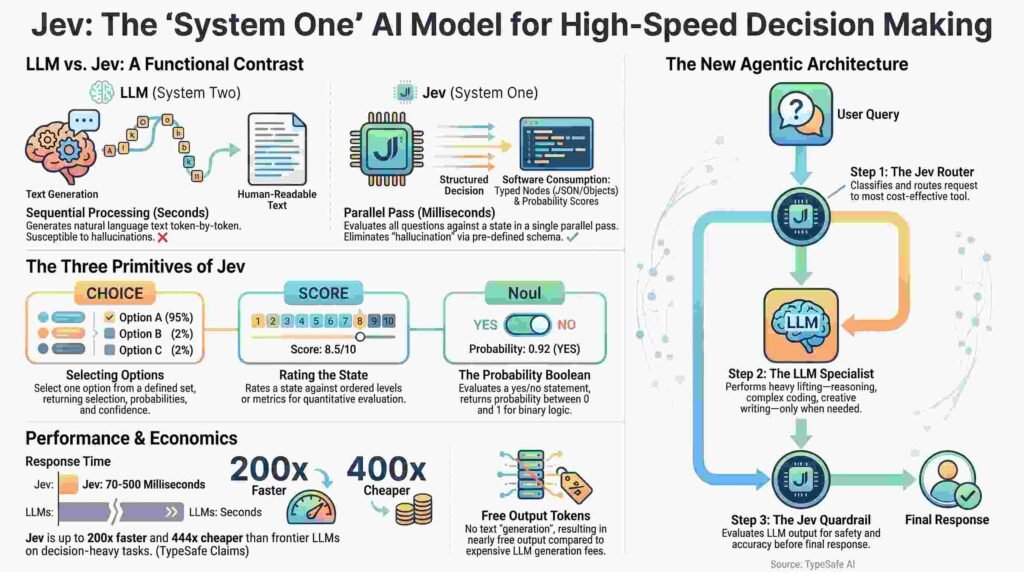
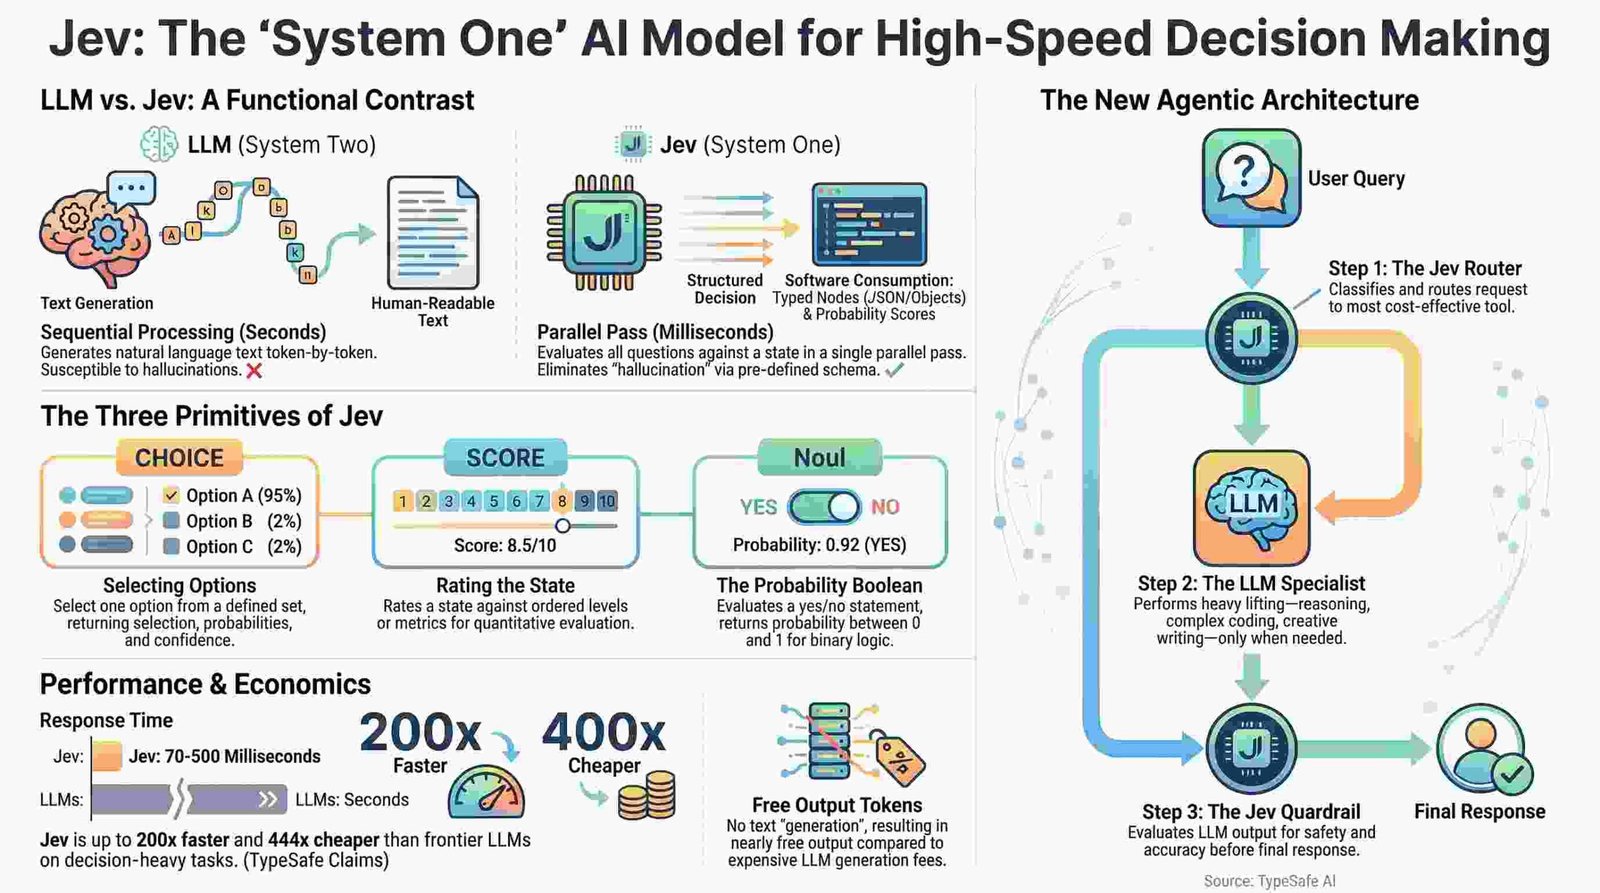
TypeSafe positions Jev as a “System One” model, a direct nod to Daniel Kahneman’s Thinking, Fast and Slow. If traditional LLMs represent System Two—the slow, deliberative, token-by-token reasoning engine—then Jev is the brain’s instinctive, parallel response system.
While at OpenAI working on ChatGPT and GPT-4, Almeida grew frustrated with the “lightning in a bottle” nature of conversational models. They were brilliant, yet architecturally ill-suited for the rigid, high-speed requirements of software infrastructure. Jev is the antithesis of the chatbot. It is trained via RLCD (Reinforcement Learning for Calibrated Decisions) on exclusively synthetic data. Unlike RLHF, which optimizes for what a human rater likes, RLCD optimizes for the accuracy of the outcome.
For developers, offloading “decisions” from “generation” is a structural breakthrough. It treats the LLM as the reasoning brain and Jev as the nervous system, capable of handling rapid-fire logic without the latency of a conversational loop.
2. Speed That Blurs the Line of Real-Time
To understand Jev’s impact, look no further than the 1993 classic Doom. To demonstrate the model’s sub-100ms latency, developers have showcased Jev playing the high-speed shooter, making instantaneous pathfinding and combat decisions that would be physically impossible for a token-generating LLM.
The performance claims, while self-reported by TypeSafe, are disruptive:
- Latency: End-to-end response times of 70 to 500 milliseconds.
- Speed: 40x to 200x faster than frontier LLMs.
- Cost: 40x to 400x cheaper than leading models.
- Peak Efficiency: Internal benchmarks recorded workflows up to 193.6x faster and 444.6x cheaper.
However, a healthy dose of journalistic skepticism is required. Despite a reported $200 million valuation and a $40 million seed round led by DCVC, TypeSafe remains a “black box.” The company has yet to release a formal white paper or open-source its weights, leading some observers to speculate whether Jev is a ground-up architecture or a highly distilled, transformer-based optimization of an existing open-weight model.
3. The Power of Primitives (Choice, Score, Noul)
Jev replaces the open-ended text box with three rigid “Primitives.” You don’t prompt it; you provide a “state” (text or JSON) and a “question.” Because the model operates on a pre-defined schema, the “hallucination” problem is solved by physical impossibility—the model cannot return a value that doesn’t fit the requested type.
| Primitive | Purpose | Returns |
| Choice | Selecting one option from a set. | The selection, probabilities, and confidence score. |
| Score | Rating state against ordered levels. | Numerical score and per-level confidence. |
| Noul | Evaluating a binary yes/no statement. | A probability value between 0 and 1. |
The “Noul” primitive is particularly clever. It isn’t a simple Boolean; it is a probability engine. The intelligence lies in the calibration of that 0-to-1 scale, allowing software to set “logical gates” based on the model’s confidence. If Jev is 99% sure an email is a security threat, the software can auto-delete; if it’s only 60% sure, it routes to a human.
4. The Jevons Paradox: Efficiency Increases Demand
Named after 19th-century economist William Stanley Jevons, the “Jevons Paradox” suggests that as a resource becomes more efficient, we don’t use less of it—we find infinitely more ways to consume it.
Jev isn’t just a “cheaper LLM”; it’s a new category of compute. We are seeing the birth of use cases that were previously discarded due to the “latency tax” of traditional AI:
- Real-time “Slop Filters”: High-speed classification of social media feeds to filter low-quality content in milliseconds.
- High-Volume Game Loops: NPCs that make complex tactical decisions without stalling the frame rate.
- Instant Infrastructure: Categorizing thousands of customer tickets or server logs per second for a fraction of a cent.
5. The “Router” Architecture
In a modern “Agentic” workflow, Jev serves as the brain’s traffic controller. Instead of firing every user query at an expensive frontier model like Claude Opus or GPT-4—which is like using a Ferrari to deliver a pizza—Jev analyzes the intent and routes the task.
In developer benchmarks, Jev has demonstrated a 96% probability of selecting the correct tool (SQL, Python, or Web Search) for a task, entirely bypassing the slow “reasoning” phase of an LLM. Because output tokens are free (since nothing is generated), the cost savings are massive. One real-world test showed that always using a frontier model was 94% more expensive than using a Jev-led router.
“He gave up writing to get the speed,” notes developer Mayank Aggarwal. “This approach makes a lot more sense… all the things which used to take a lot of time with your LLM are being done at god speed.”
6. Verification and Guardrails
The final piece of the Jev architecture is the “Output Judge.” Currently, verifying an LLM’s output requires a second, equally expensive LLM pass to check for errors. Jev can act as a high-speed “logical gate” at the end of the pipeline. It evaluates the LLM’s response against safety and quality metrics to decide: Accept or Regenerate? This creates a self-healing AI architecture that ensures reliability without doubling the latency.
Conclusion: The Silent Future of Intelligence
The launch of Jev marks a fundamental shift in our relationship with machine intelligence. We are moving away from AI as a loquacious chatbot and toward AI as an invisible, high-speed decision engine embedded in the very plumbing of our software.
By sacrificing the ability to speak, Jev has gained the ability to act at the speed of code. As the cost of a decision drops to near-zero and the speed becomes instantaneous, we have to ask: which parts of your daily workflow will you finally be brave enough to hand over to a machine?
Jev is currently in limited early access. Developers can join the waitlist at TypeSafe.ai.
Discover more from TechResider Submit AI Tool
Subscribe to get the latest posts sent to your email.